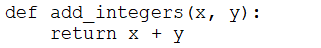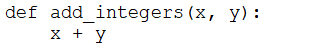Limited-Time Offer: Enjoy 50% Savings! Ends in 00h 00m 00s Coupon code: 50OFF
Skip to content

Free Databricks Certified Data Engineer Associate Exam Databricks-Certified-Data-Engineer-Associate Exam Questions

Page: 1 / 16 Total 231 questions

Want more questions? Get Premium Access.

Question 1

A data engineer is attempting to drop a Spark SQL table my_table. The data engineer wants to delete all table metadata and data.

They run the following command:

DROP TABLE IF EXISTS my_table

While the object no longer appears when they run SHOW TABLES, the data files still exist.

Which of the following describes why the data files still exist and the metadata files were deleted?

Correct Answer: C. The table was external
Explanation:

An external table is a table that is defined in the metastore and points to an existing location in the storage system. When you drop an external table, only the metadata is deleted from the metastore, but the data files are not deleted from the storage system. This is because external tables are meant to be shared by multiple applications and users, and dropping them should not affect the data availability. On the other hand, a managed table is a table that is defined in the metastore and also managed by the metastore. When you drop a managed table, both the metadata and the data files are deleted from the metastore and the storage system, respectively. This is because managed tables are meant to be exclusive to the application or user that created them, and dropping them should free up the storage space. Therefore, the correct answer is C, because the table was external and only the metadata was deleted when the table was dropped.Reference:Databricks Documentation - Managed and External Tables,Databricks Documentation - Drop Table
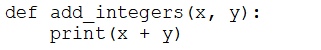
Question 2

A data engineer configures a Databricks Lakeflow Job for daily customer data processing:

Entry task: A single notebook loads raw data.

Parallel tasks:

A SQL query task performs data cleansing.

A notebook task performs feature engineering.

A pipeline task performs model updates.

Exit task: A dashboard refresh must run after all parallel tasks complete.

Requirement: Implement this dependency pattern using a DAG-based task graph.

Which task configuration ensures that all parallel tasks complete before the dashboard refresh task runs?

Correct Answer: B. Add the dashboard task as dependent on all three parallel tasks using fan-in control flow.

Question 3

A data engineer is troubleshooting two different pipeline failures:

Pipeline A fails with a java.lang.OutOfMemoryError immediately after display(df.collect()) is called on a 100 GB dataset.

Pipeline B fails during a wide transformation joining two large tables, with an ExecutorLostFailure message indicating executor-memory exhaustion during the shuffle.

Which action should the data engineer take to address these two issues?

Correct Answer: D. For Pipeline A, address driver memory by removing the full collect() or increasing driver capacity; for Pipeline B, increase shuffle partitions or executor memory.

Question 4

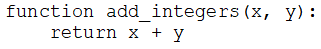
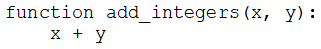
A data engineer that is new to using Python needs to create a Python function to add two integers together and return the sum?

Which of the following code blocks can the data engineer use to complete this task?

A)

B)

C)

D)

E)

Correct Answer: D. Option D
Explanation:

https://www.w3schools.com/python/python_functions.asp

https://www.geeksforgeeks.org/python-functions/


Question 5

A data engineer has configured a Lakeflow Job that runs daily to ingest customer transaction data from a legacy relational database. The extracted data must be written directly to a Unity Catalog table and be immediately queryable through SQL. The team must also preserve data lineage.

Which action enables this ingestion with direct landing in Unity Catalog, preserved lineage, and immediate SQL query capability?

Correct Answer: B. Use spark.read.format('jdbc') and write the resulting DataFrame with saveAsTable('catalog.schema.table')

Question 6

Identify how the count_if function and the count where x is null can be used

Consider a table random_values with below data.

What would be the output of below query?

select count_if(col > 1) as count_

a. count(*) as count_b.count(col1) as count_c from random_values col1

0

1

2

NULL -

2

3

Correct Answer: A. 3 6 5

Question 7

A Databricks single-task workflow fails at the last task due to an error in a notebook. The data engineer fixes the mistake in the notebook. What should the data engineer do to rerun the workflow?

Correct Answer: A. Repair the task

Question 8

A data engineering team is designing the Gold layer in its Unity Catalog-governed lakehouse for downstream BI and analytics users. The team wants to expose business-ready metrics with fast query performance and consistent definitions while keeping the transformation logic in Spark notebooks.

Which type of Gold-layer object meets this requirement?

Correct Answer: A. A materialized view that precomputes aggregations from Silver tables on a schedule and is queried by BI tools for faster, consistent analytics

Question 9

A data engineer is running code in a Databricks Repo that is cloned from a central Git repository. A colleague of the data engineer informs them that changes have been made and synced to the central Git repository. The data engineer now needs to sync their Databricks Repo to get the changes from the central Git repository.

Which of the following Git operations does the data engineer need to run to accomplish this task?

Correct Answer: C. Pull
Explanation:

To sync a Databricks Repo with the changes from a central Git repository, the data engineer needs to run the Git pull operation. This operation fetches the latest updates from the remote repository and merges them with the local repository. The data engineer can use the Pull button in the Databricks Repos UI, or use the git pull command in a terminal session. The other options are not relevant for this task, as they either push changes to the remote repository (Push), combine two branches (Merge), save changes to the local repository (Commit), or create a new local repository from a remote one (Clone).Reference:

Run Git operations on Databricks Repos

Git pull


Question 10

A data engineering team needs to integrate two data sources into Databricks:

Clickstream events: 5,000 events per second from an Apache Kafka topic

Customer master data: Only changed records every four hours from a Snowflake database

The solution must process clickstream data with latency under 30 seconds and prevent reprocessing customer master data that has not changed.

Which ingestion approach meets these requirements?

Correct Answer: A. Use Structured Streaming for Kafka and a Lakeflow Connect managed connector with incremental processing for Snowflake.

Question 11

An engineering manager wants to monitor the performance of a recent project using a Databricks SQL query. For the first week following the project's release, the manager wants the query results to be updated every minute. However, the manager is concerned that the compute resources used for the query will be left running and cost the organization a lot of money beyond the first week of the project's release.

Which of the following approaches can the engineering team use to ensure the query does not cost the organization any money beyond the first week of the project's release?

Correct Answer: E. They can set the query's refresh schedule to end on a certain date in the query scheduler.
Explanation:

In Databricks SQL, you can use scheduled query executions to update your dashboards or enable routine alerts. By default, your queries do not have a schedule. To set the schedule, you can use the dropdown pickers to specify the frequency, period, starting time, and time zone. You can also choose to end the schedule on a certain date by selecting the End date checkbox and picking a date from the calendar. This way, you can ensure that the query does not run beyond the first week of the project's release and does not incur any additional cost. Option A is incorrect, as setting a limit to the number of DBUs does not stop the query from running. Option B is incorrect, as there is no option to end the schedule after a certain number of refreshes. Option C is incorrect, as there is a way to ensure the query does not cost the organization money beyond the first week of the project's release. Option D is incorrect, as setting a limit to the number of individuals who can manage the query's refresh schedule does not affect the query's execution or cost.Reference:Schedule a query,Schedule a query - Azure Databricks - Databricks SQL


Question 12

A data engineer is decommissioning a sandbox schema in Unity Catalog. Some tables are ephemeral staging outputs that can be safely removed entirely, but a few tables point at shared cloud storage used by downstream jobs outside Databricks. The engineer must avoid deleting any shared files when cleaning up catalog objects.

How does Unity Catalog behave when dropping Managed vs External tables?

Correct Answer: C. Drop managed staging tables to remove data and metadata, and drop external tables to remove only metadata
Explanation:

In Unity Catalog, managed tables and external tables have different lifecycle behavior. When you drop a managed table, Databricks removes the table metadata and also schedules deletion of the underlying managed data files according to the managed-table retention behavior. By contrast, when you drop an external table, Unity Catalog removes only the table metadata and does not delete the underlying files in cloud storage. This distinction exists specifically so that external data can remain available to systems outside Databricks. In the scenario described, ephemeral staging outputs that should disappear completely are best represented by managed tables, while tables backed by shared cloud storage should be external tables so that dropping them does not remove files used by downstream jobs. Therefore, option C is the correct answer. Options A, B, and D contradict documented Unity Catalog behavior because external table files are not automatically deleted, while managed table data is lifecycle-managed by Databricks.


Question 13

Which of the following data workloads will utilize a Gold table as its source?

Correct Answer: D. A job that queries aggregated data designed to feed into a dashboard
Explanation:

A Gold table is a table that contains highly refined and aggregated data that powers analytics, machine learning, and production applications. It represents data that has been transformed into knowledge, rather than just information. A Gold table is typically the final output of a medallion lakehouse architecture, where data flows from Bronze to Silver to Gold tables, with each layer improving the structure and quality of data. A job that queries aggregated data designed to feed into a dashboard is an example of a data workload that will utilize a Gold table as its source, as it requires data that is ready for consumption and analysis. The other options are either data workloads that will use a Bronze or Silver table as their source, or data workloads that will produce a Gold table as their output.Reference:Databricks Documentation - What is the medallion lakehouse architecture?,Databricks Documentation - What is a Medallion Architecture?,K21Academy - Delta Lake Architecture & Azure Databricks Workspace.


Question 14

A data engineer wants to create a relational object by pulling data from two tables. The relational object does not need to be used by other data engineers in other sessions. In order to save on storage costs, the data engineer wants to avoid copying and storing physical data.

Which of the following relational objects should the data engineer create?

Correct Answer: D. Temporary view
Explanation:

A temporary view is a relational object that is defined in the metastore and points to an existing DataFrame. It does not copy or store any physical data, but only saves the query that defines the view. The lifetime of a temporary view is tied to the SparkSession that was used to create it, so it does not persist across different sessions or applications. A temporary view is useful for accessing the same data multiple times within the same notebook or session, without incurring additional storage costs. The other options are either materialized (A, E), persistent (B, C), or not relational objects .Reference:Databricks Documentation - Temporary View,Databricks Community - How do temp views actually work?,Databricks Community - What's the difference between a Global view and a Temp view?,Big Data Programmers - Temporary View in Databricks.


Question 15

A data engineer needs to develop integration tests for an ETL process and deploy a version-controlled, packaged workflow into production using an external job scheduler.

Which tool should the data engineer use for this job?

Correct Answer: B. Databricks Asset Bundles
Explanation:

Databricks Asset Bundles provide a modern, declarative approach to defining, testing, and deploying Databricks workflows as version-controlled code artifacts. Using YAML configuration files, engineers can describe jobs, pipelines, dependencies, and environments in a structured and reproducible way. Asset Bundles integrate well with CI/CD pipelines and external schedulers, enabling teams to package workflows, run integration tests, and deploy consistently across environments such as development, staging, and production. This aligns directly with the requirement for version control and external orchestration. The Databricks CLI (A) is primarily used as a deployment interface but does not provide the structured packaging and workflow definition capabilities of Asset Bundles. Databricks Connect (C) is intended for local development and testing of Spark code, not workflow deployment. The Databricks SDK (D) provides programmatic access to APIs but lacks the declarative, packaged deployment model required here. Databricks documentation positions Asset Bundles as the recommended solution for production-grade workflow deployment and testing within modern data engineering practices.