
Limited-Time Offer: Enjoy 50% Savings! Ends in 00h 00m 00s Coupon code: 50OFF
Skip to content

Free Databricks Certified Machine Learning Professional Databricks-Machine-Learning-Professional Exam Questions

Page: 1 / 6 Total 60 questions

Want more questions? Get Premium Access.

Question 1

A data scientist is using MLflow to track their machine learning experiment. As a part of each MLflow run, they are performing hyperparameter tuning. The data scientist would like to have one parent run for the tuning process with a child run for each unique combination of hyperparameter values.

They are using the following code block:
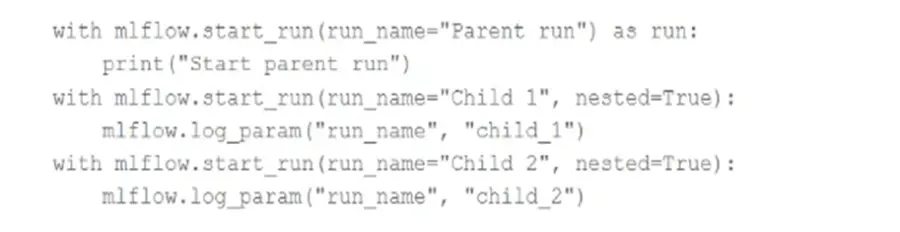
The code block is not nesting the runs in MLflow as they expected.

Which of the following changes does the data scientist need to make to the above code block so that it successfully nests the child runs under the parent run in MLflow?

Correct Answer: E. Add the nested=True argument to the parent run and remove the nested=True arguments from the child runs
Question 2

Which of the following is a reason for using Jensen-Shannon (JS) distance over a Kolmogorov-Smirnov (KS) test for numeric feature drift detection?

Correct Answer: D. JS is more robust when working with large datasets

Question 3

A machine learning engineer has deployed a model recommender using MLflow Model Serving. They now want to query the version of that model that is in the Production stage of the MLflow Model Registry.

Which of the following model URIs can be used to query the described model version?

Correct Answer: B. The version number of the model version in Production is necessary to complete this task.

Question 4

In a continuous integration, continuous deployment (CI/CD) process for machine learning pipelines, which of the following events commonly triggers the execution of automated testing?

Correct Answer: D. The launch of a new cost-efficient job cluster

Question 5

A machine learning engineer has developed a model and registered it using the FeatureStoreClient fs. The model has model URI model_uri. The engineer now needs to perform batch inference on customer-level Spark DataFrame spark_df, but it is missing a few of the static features that were used when training the model. The customer_id column is the primary key of spark_df and the training set used when training and logging the model.

Which of the following code blocks can be used to compute predictions for spark_df when the missing feature values can be found in the Feature Store by searching for features by customer_id?

Correct Answer: E. fs.score_batch(model_uri, spark_df)

Question 6

Which of the following describes concept drift?

Correct Answer: D. Concept drift is when there is a change in the distribution of the predicted target given by the model

Question 7

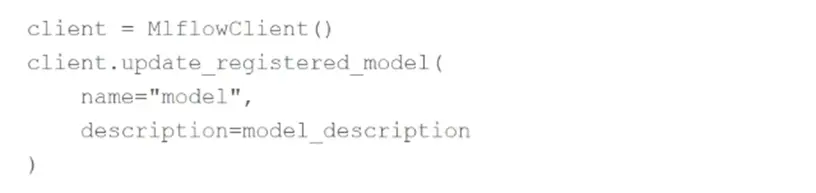
A machine learning engineering manager has asked all of the engineers on their team to add text descriptions to each of the model projects in the MLflow Model Registry. They are starting with the model project "model" and they'd like to add the text in the model_description variable.

The team is using the following line of code:

Which of the following changes does the team need to make to the above code block to accomplish the task?

Correct Answer: B. There no changes necessary

Question 8

A machine learning engineer is migrating a machine learning pipeline to use Databricks Machine Learning. They have programmatically identified the best run from an MLflow Experiment and stored its URI in the model_uri variable and its Run ID in the run_id variable. They have also determined that the model was logged with the name "model". Now, the machine learning engineer wants to register that model in the MLflow Model Registry with the name "best_model".

Which of the following lines of code can they use to register the model to the MLflow Model Registry?

Correct Answer: D. mlflow.register_model(model_uri, 'model')

Question 9

A machine learning engineering team has written predictions computed in a batch job to a Delta table for querying. However, the team has noticed that the querying is running slowly. The team has already tuned the size of the data files. Upon investigating, the team has concluded that the rows meeting the query condition are sparsely located throughout each of the data files.

Based on the scenario, which of the following optimization techniques could speed up the query by colocating similar records while considering values in multiple columns?

Correct Answer: E. Tuning the file size

Question 10

A machine learning engineer is in the process of implementing a concept drift monitoring solution. They are planning to use the following steps:

1. Deploy a model to production and compute predicted values

2. Obtain the observed (actual) label values

3. _____

4. Run a statistical test to determine if there are changes over time

Which of the following should be completed as Step #3?

Correct Answer: D. None of these should be completed as Step #3